Building the Learning Loop: The Architecture of an Agent That Actually Improves
Most of the argument about AI agents is still about whether they can act. Inside our fleet that question is settled. The harder one is whether an agent gets better, and the answer turns out to be an argument about where a lesson should live.

An AI agent can act without ever improving. Our company-scoped oracle selects among 16 tools on its own, writes to a client's database, triggers other agents' analyses, and files tickets against the platform that nobody asked it to file. That is agency under any working definition, and none of it requires the system to remember yesterday. Left alone, it would start every morning as capable and as ignorant as the morning before. Acting and improving are different capabilities, built from different parts, and confusing them is the most common conceptual error in the conversation about agents. This essay is about the second one, and the answer turns out to be an argument about where a lesson should live.
Agency and learning are different axes, not stages
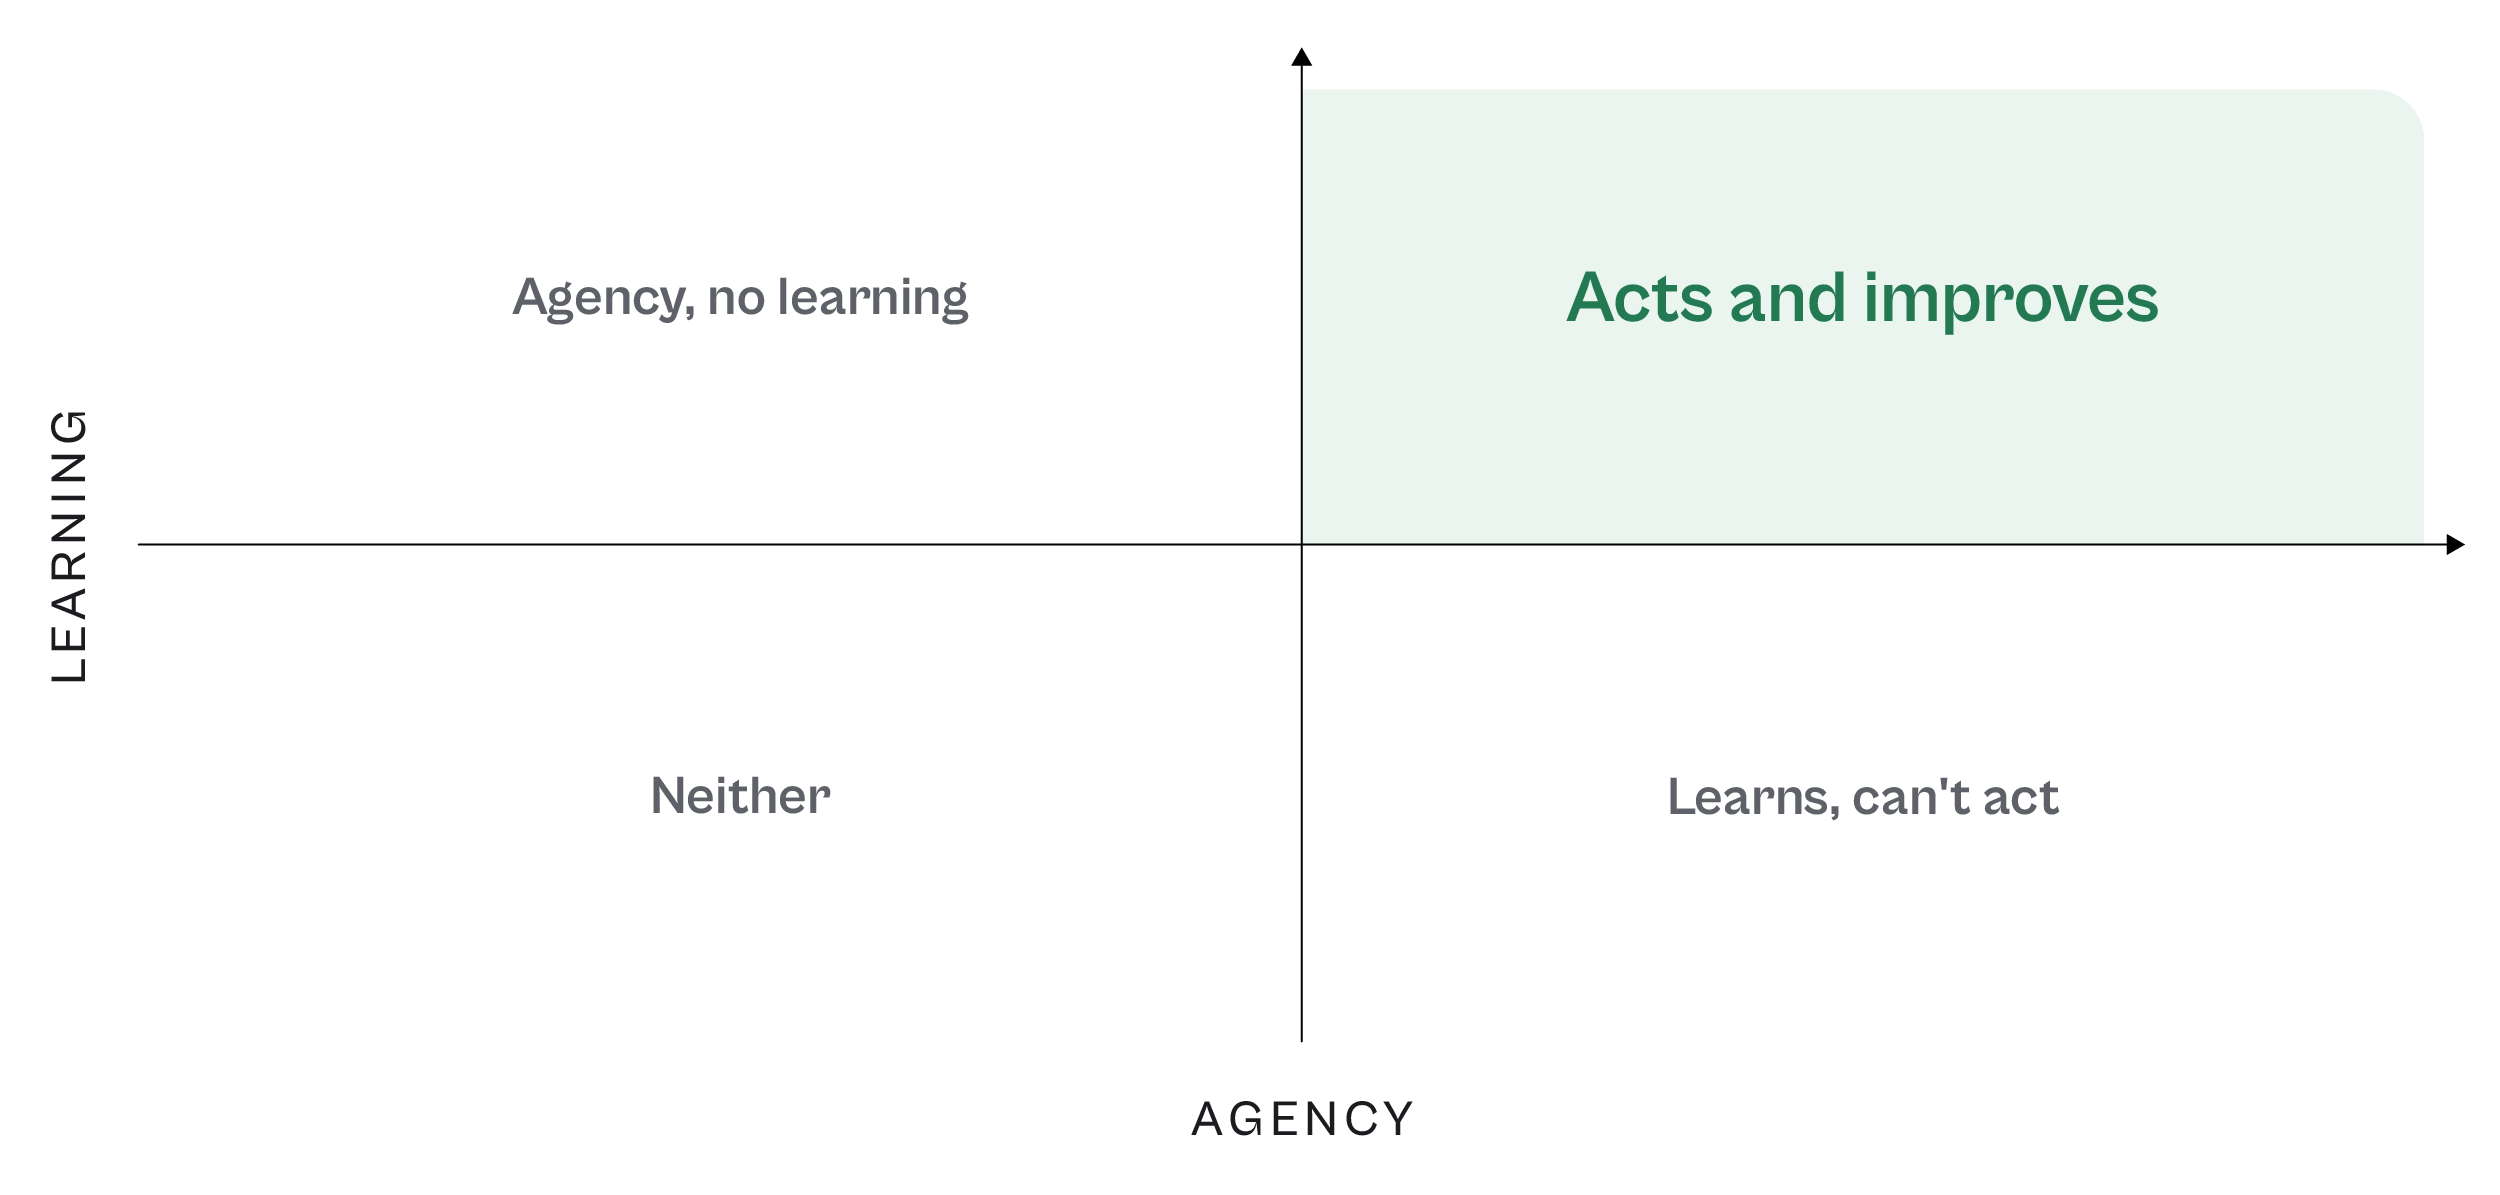
Seven capabilities matter here, and they divide into two groups. Four belong to agency: perception, which means reading live state rather than a snapshot handed to it; action, which means changing state rather than describing it; autonomy, which means choosing the next step from what it just observed; and delegation, which means invoking another agent and reading back its judgment. Three belong to learning: persistence, carrying knowledge across sessions rather than starting cold; self-knowledge, holding an accurate account of its own track record; and adaptation, changing behavior from accumulated experience rather than from an edited prompt.
The two axes are orthogonal, and treating them as a single ladder is the error. A system can hold all four agency capabilities and none of the learning ones and still be an agent in every sense that matters. So the goal was never to make our agents more agentic. They act. The goal is making them improve, and that is a different engineering problem with a different shape and a different hard part.
A correction is a training record
Every correction a reviewer makes to an agent's output is a record of the distance between what the agent produced and what the firm was willing to publish. Accumulate those corrections and they compose an increasingly exact portrait of excellence in one category of work, and that portrait is the material a more capable agent is built from. We have made that claim before as a design commitment stated in prose. What follows is the engineering, including the parts that turned out harder than the prose implied.
Learning needs five primitives, installed at one place
Every structured agent in the fleet already flows through a single entry point. That function owns the safety and cost controls so no caller has to: in-flight deduplication, cooldowns, freshness windows, eligibility gating, transient retry, and tenant stamping on every run. Learning belongs at the same chokepoint for the same reason. A capability installed once where everything passes is a capability every agent has. A capability installed per agent is a capability that three agents have, in three slightly different ways, none of which anyone can reason about.
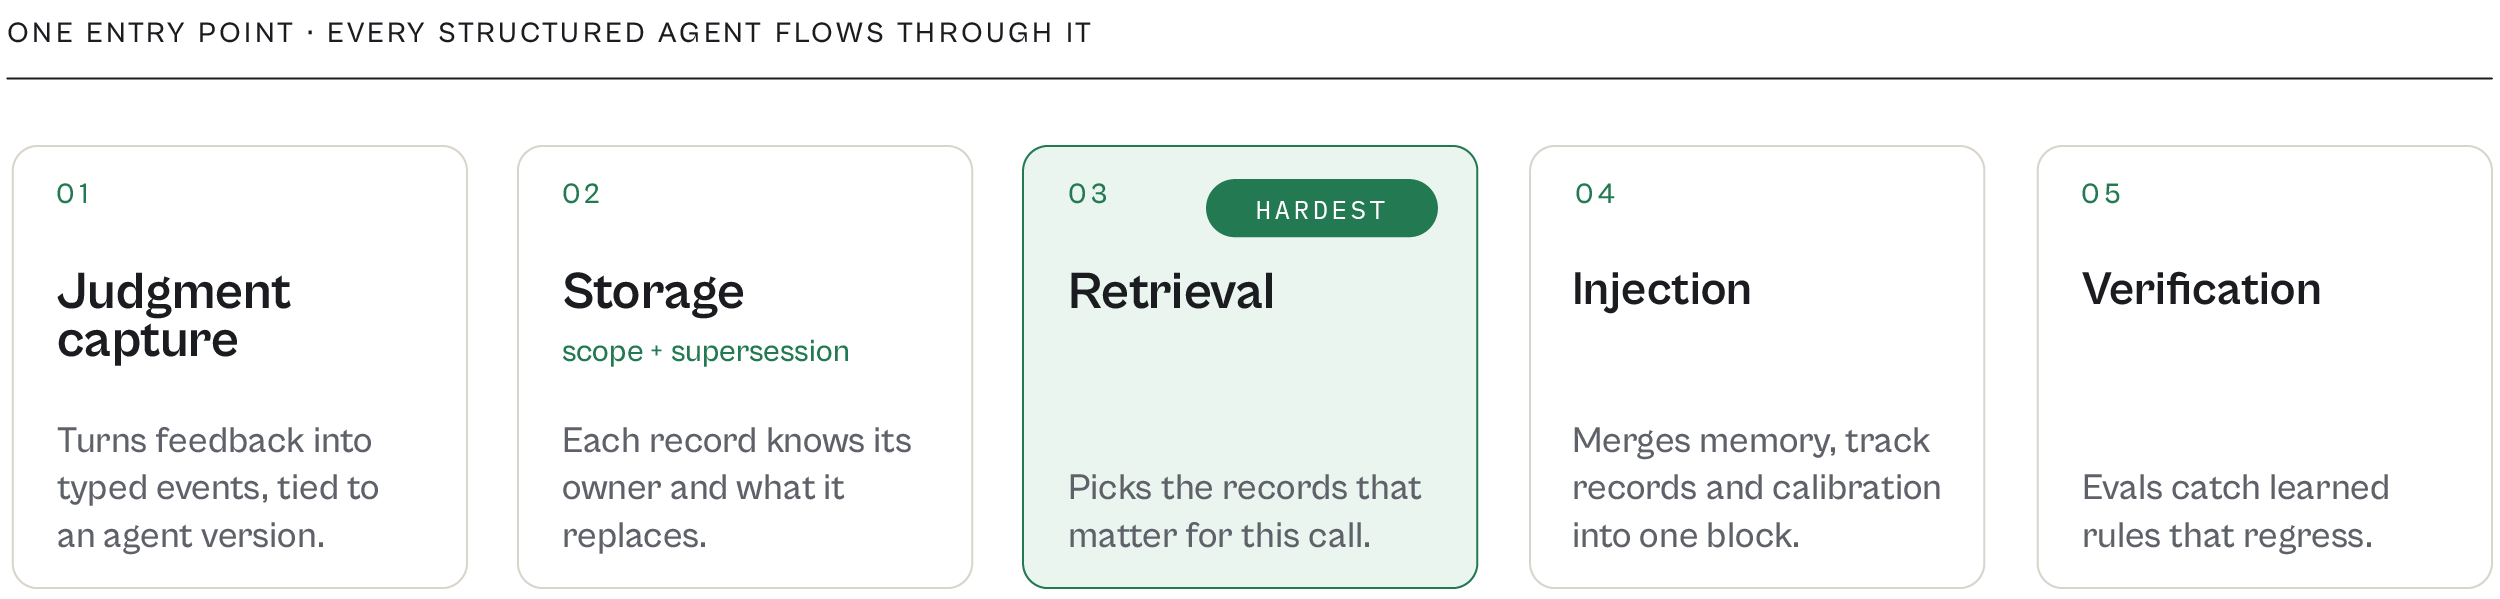
| Primitive | What it does | What breaks without it |
|---|---|---|
| Judgment capture | Normalizes three moments that look unrelated into one typed event: a user correcting an agent mid-conversation, reality resolving a claim it made months ago, a person accepting or rejecting an extraction. Each record is attributed to an agent and a version | Feedback exists and can't be attributed, so a lesson learned about last quarter's prompt gets silently applied to this quarter's |
| Storage with scope and supersession | A record knows whose it is and what it replaces | An append-only store accumulates contradictions and resolves them by accident of retrieval order, confidently applying a rule the firm retired six months ago |
| Retrieval | Selects the few records that belong in this specific invocation, for this company, at this moment | Every other primitive works and nothing useful arrives. This is the hardest of the five by a wide margin |
| Injection | One function assembles firm memory, the agent's own track record, cross-firm platform calibration, and learned rules into a single block the agent reads | Each agent builds its own fragment in its own way, and nobody can say what any given agent actually saw when it made a call |
| Verification | Evaluations, so a learned rule cannot silently regress | The system gets worse in ways nobody notices, which is a worse outcome than not learning at all |
The fifth is the one teams skip and the one that makes the rest safe. It is the same principle that governs our delivery pipeline: no output is trusted because the thing that produced it was confident. It is trusted because a check went green. The third is where the actual difficulty lives.
Retrieval is the whole problem, and storage is not
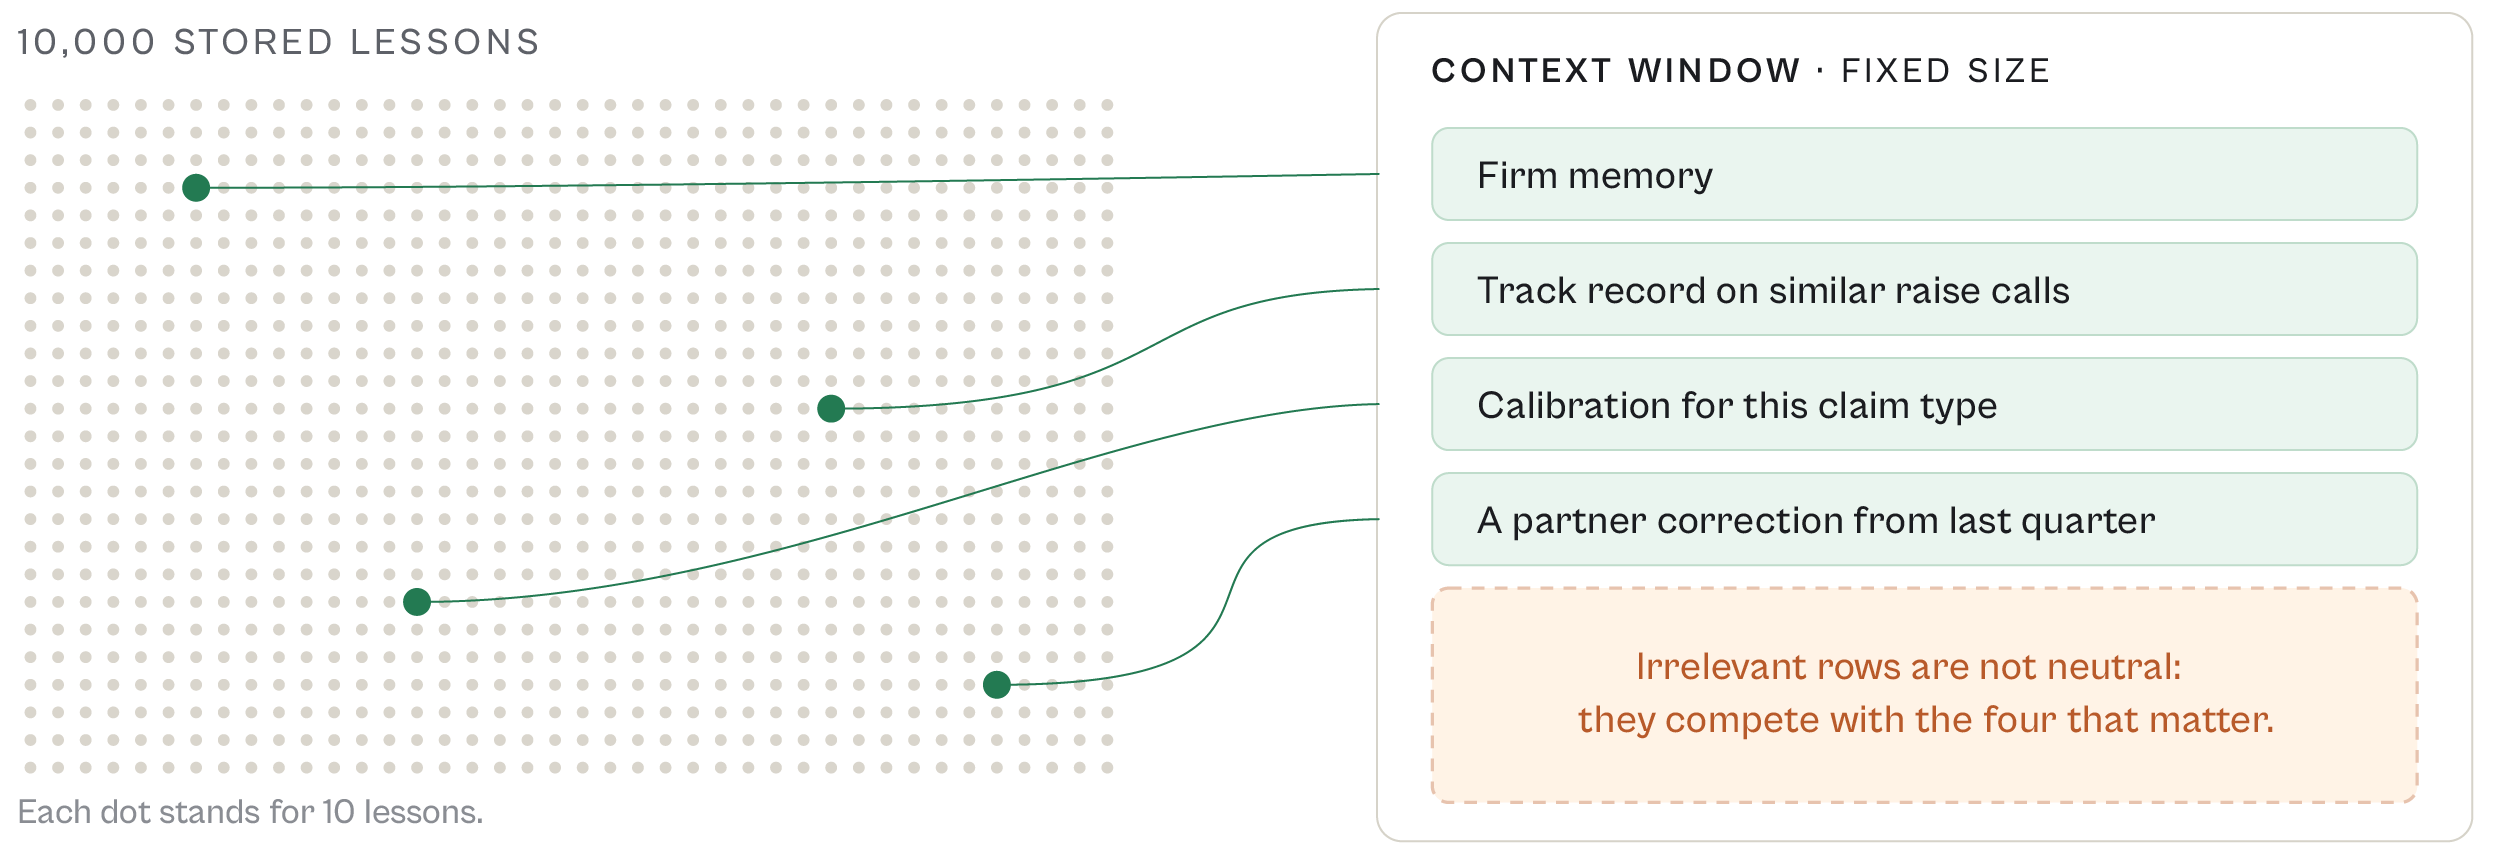
Storing 10,000 lessons is trivial. Any relational database will hold them, indexed and scoped, without complaint. The difficulty arrives one step later, when an agent is invoked and something has to decide which four of those 10,000 belong in this context window, for this company, at this moment.
This is an attention problem, and it took us a while to see it. A model's context window is enormously larger than human working memory, and it is still a fixed denominator. Injecting more of a badly ranked corpus makes an agent worse rather than better, for the same reason that adding one more panel to a dashboard makes a partner slower: irrelevant material is not neutral, it competes. Precision in retrieval is the same discipline as restraint in an interface, practiced on a different reader.
Our current ranking is a salience heuristic: recency multiplied by frequency multiplied by a source weight. It is a reasonable first version and we don't expect it to hold past a few hundred rows in a single scope, because a heuristic that never reads the question can't know that a lesson about revenue recognition is irrelevant to a conversation about key-person risk. The eventual answer is semantic rather than heuristic, which means vectorizing memory and learning records so that retrieval matches on meaning, and so later clustering can group lessons by what they actually say.
A lesson should end up as hard as it can get
Knowledge in a system like this can live in five places, and they are not equivalent. Ranked from the softest to the hardest, where hardness means how reliably a lesson stored there actually governs behavior:
| Layer | Holds | Nature |
|---|---|---|
| Database rows | Memory, calibration, track record | Retrieved per invocation. The softest substrate, and conditional on the retrieval step succeeding |
| Tool descriptions | When and how to act | A contextual hint, read only while the agent is choosing among tools |
| System prompt | Behavioral rules, identity | A strong hint. Present on every invocation, and still a hint |
| Code | Deterministic domain logic | A guarantee |
| Model weights | General capability | Outside the ladder. Not ours to write, and not where any of this is going |
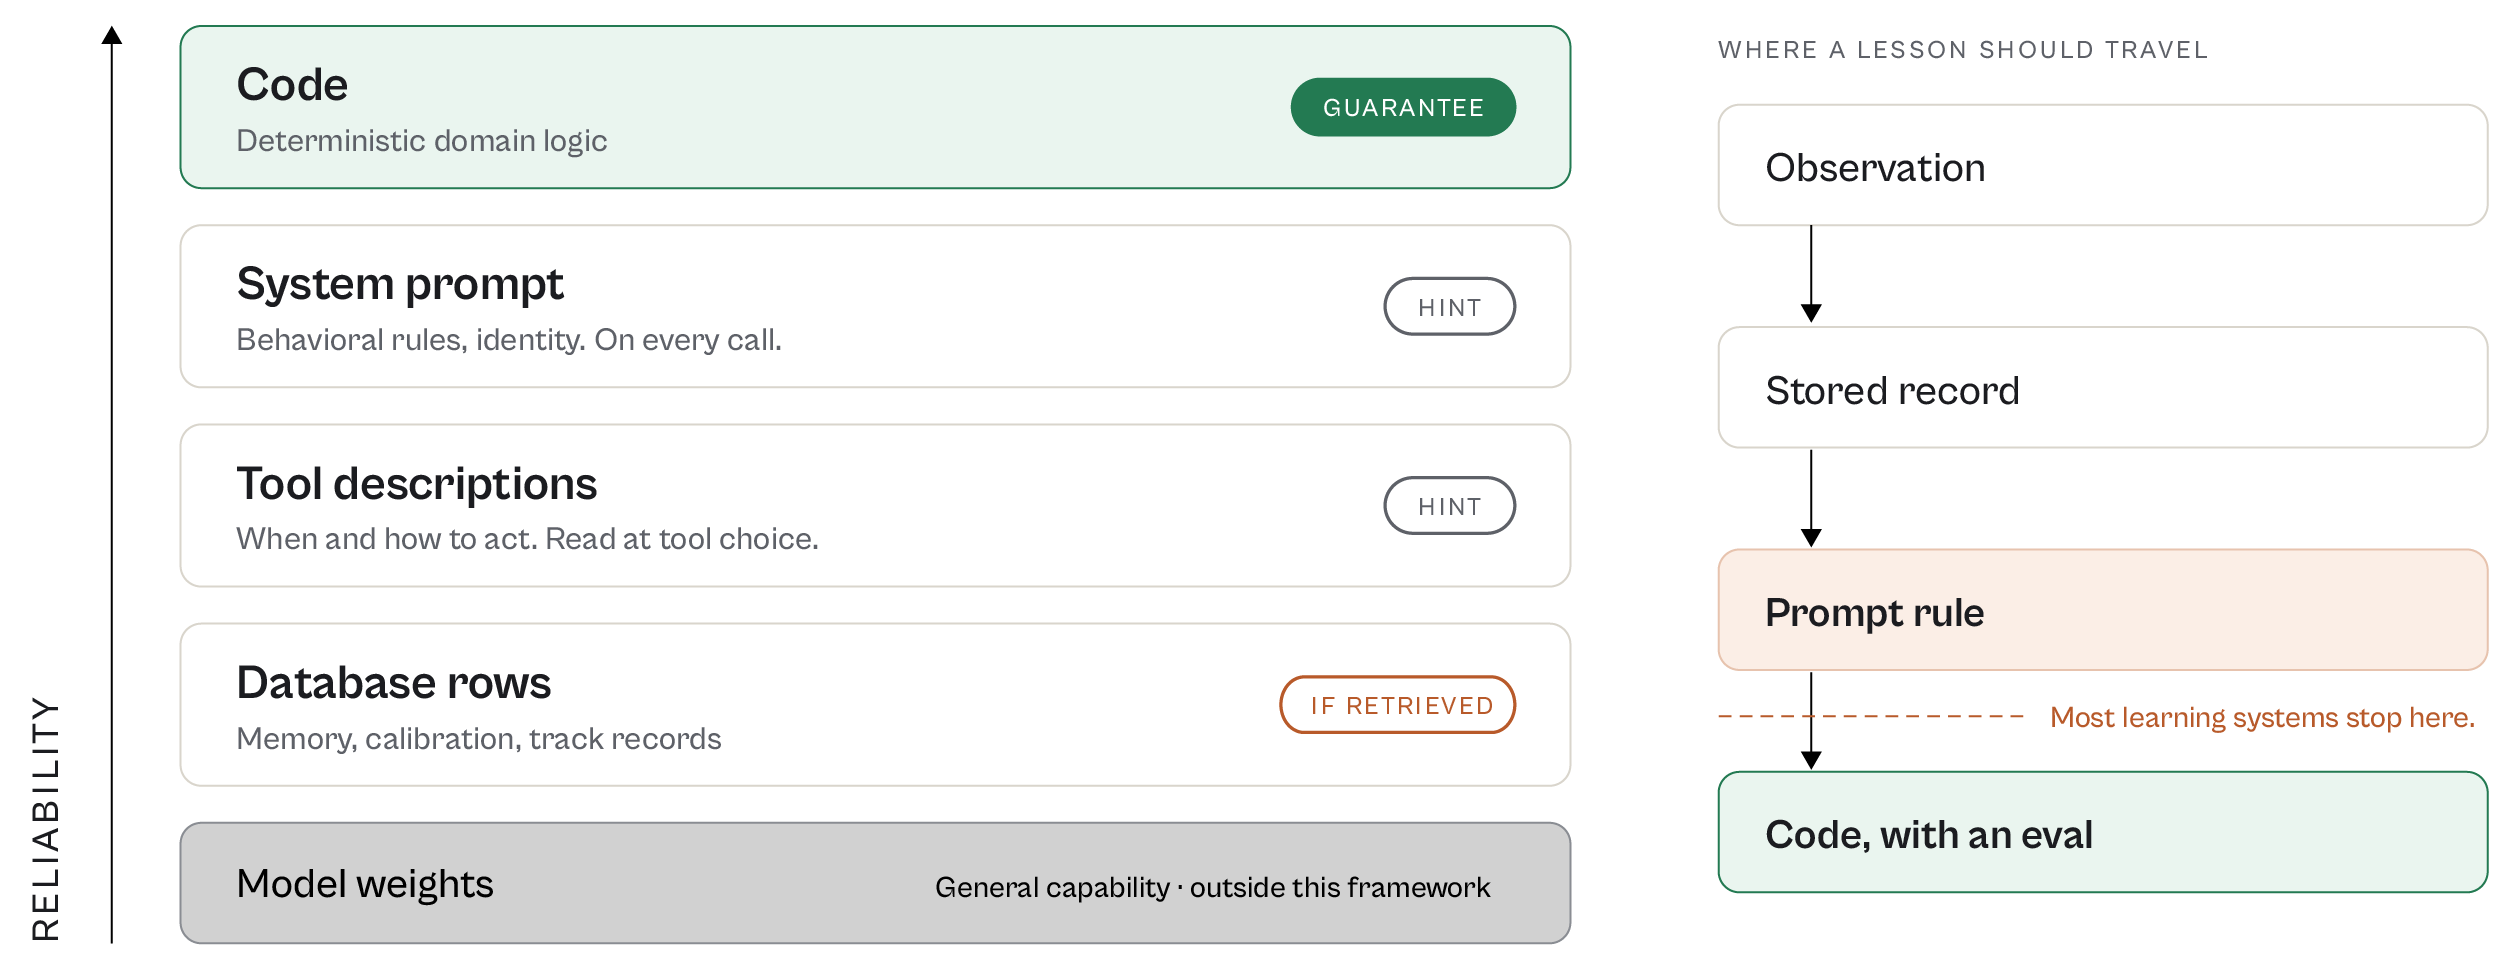
The direction of travel is the whole point. A lesson begins as an observation, becomes a stored record, and may eventually be promoted into a prompt rule. Most learning systems being built today stop exactly there, and treat an accumulated pile of prompt rules as the finished product of learning. We think the better destination, for most lessons, is one layer harder.
Take a real one. When several valuation letters share the same date of value, they should be summed rather than treated as competing marks. That is not a matter of judgment. It is arithmetic with a condition attached, and it is correct every time the condition holds. Written into the valuation read path, it is simply true. Written as a line in a prompt, it is a request that a model comply, and a model complies most of the time, which is a different and much worse property for a figure that ends up in an LP letter.
A lesson in a prompt is a hope that the model complies. The same lesson in code is true every time.
A learning system that only writes prompt rules leaves most of its value behind
So promotion carries a discipline, and it is a single question asked before anything else: can this lesson be encoded deterministically? If the answer is yes, it belongs in code and it arrives with an evaluation attached. Only the judgment-shaped lessons, the ones that require reading intent or weighing incommensurable things, stay as prompt rules, and there are fewer of those than most teams expect once they start sorting honestly.
This is the same split that already governs the fleet, applied to learning instead of analysis. Our Follow-On Advisor is barred from arithmetic: four valuation methods are computed in code, and the model's contribution is how to weight them. Round Radar may move a deterministic base probability by at most a fifth of the way in either direction, and only with a named reason. The rule in both cases is that the model handles judgment and code handles anything that must be exact. A learning system that only ever produces prompt lines routes every lesson to the judgment side regardless of its shape, which is the same error in a new place.
The ladder also answers a fair objection. If agents improve by accumulating rules in their prompts, then a mature agent is a system governed by a long, unaudited pile of accreted instructions that nobody has read end to end. That is a real failure mode, and promotion is what prevents it. A prompt that stays short because most of its lessons graduated into code is a prompt a person can still reason about.
Three tempting answers, and why we declined each
Each of these is a reasonable response to something real, which is why capable teams reach for them.
Fine-tune a model on the firm's data. What it gets right: weights really are the most durable substrate, and fine-tuning encodes a domain more deeply than any prompt. Where it breaks: it requires pooling examples across firms, which is exactly what our isolation architecture forbids. And a fine-tune can't be read, versioned per firm, attributed, or deleted on request, which are not optional properties for institutional capital.
Add a graph database, because the knowledge is a graph. What it gets right: the knowledge really is a graph. Company to tranche to realization, rule superseding rule, a lesson corroborated across firms. The shape is correct. Where it breaks: graph databases earn their cost at millions of edges and deep multi-hop traversals, and we have neither. At our volume it buys elegance and costs a second system to keep tenant-isolated, which is a poor trade in an architecture whose entire premise is isolation. Model the edges as rows and traverse them in application code.
Store more and inject more of it. What it gets right: memory is the right substrate, and an agent with more of the relevant history reasons better than one with less. Where it breaks: the constraint is the context window, not the disk. More retrieval is only better when retrieval is good, and past that point every additional row competes with the ones that matter.
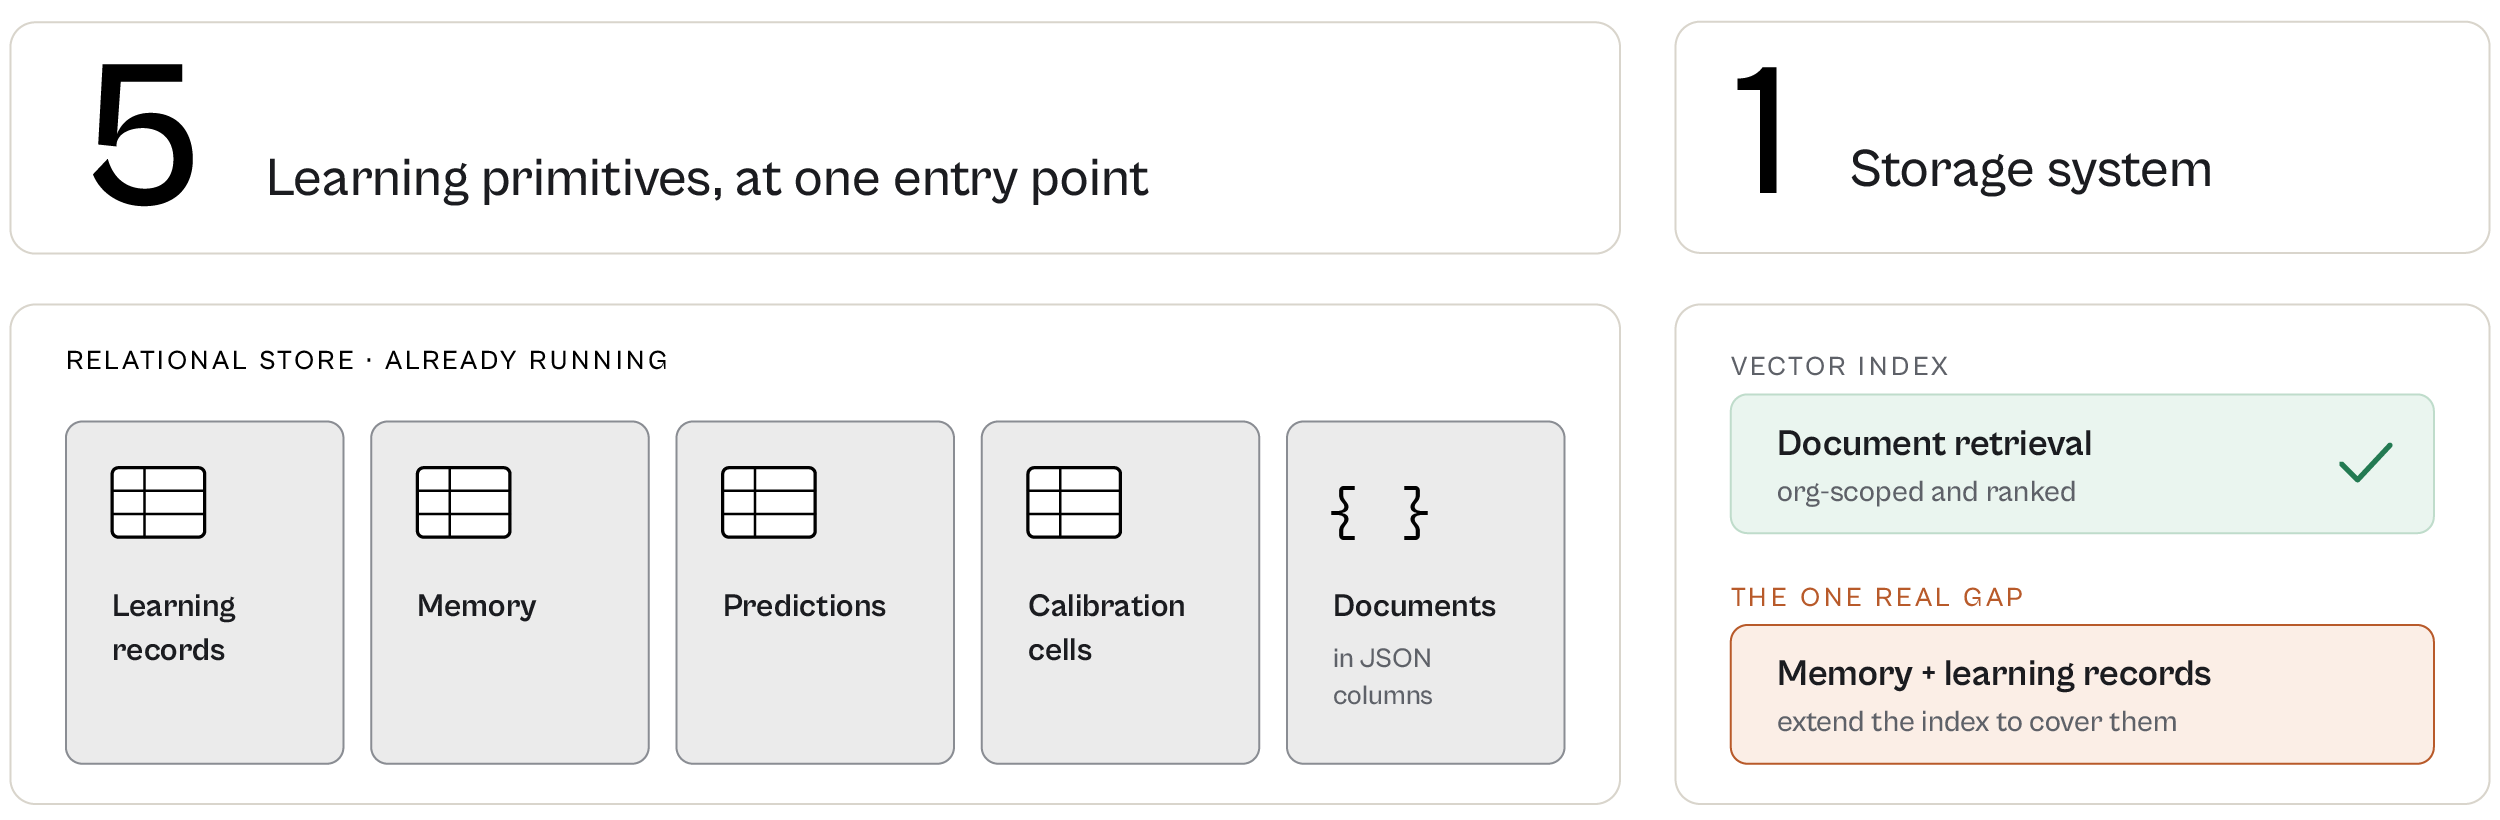
Beyond those three, the infrastructure question resolves quickly, which is worth knowing because it is where these conversations usually begin. Learning records, memory, predictions, and calibration cells are all naturally tabular and live in the relational store we already run. Documents ride JSON columns. A vector index already serves document retrieval, org-scoped and ranked, and extending it to memory and learning records is the one real gap in the design. Five primitives at one entry point, one storage system we already run, and zero new models. The hard engineering is retrieval and the promotion ladder.
Isolation is the reason we don't fine-tune
The storage judgments above could be revisited at scale. The fine-tuning decision is architectural, and it doesn't move. Multi-tenancy makes training-data collection the hard problem: gathering the examples a fine-tune would need means pooling material across firms, and pooling raw material across firms is exactly what the system was designed to make impossible. There is no cross-firm leakage because there is no cross-firm. Here, on the learning side, that guarantee costs us something real, and we pay it.
There is one intentional exception, and it belongs in the open rather than in a footnote. Platform calibration aggregates resolved predictions across firms so that every client benefits from the fleet's accuracy record. What crosses the boundary is a shape rather than an example: when the fleet forecasts a raise probability in a given band at a given stage, how often does the raise actually happen. The fencing is deliberately severe. A cell is exposed only past hard re-identification floors, meaning a minimum of 20 resolved claims, at least three distinct contributing firms, and stability across two consecutive recomputations. Only aggregate statistics cross. No per-firm value is ever written, logged, or serialized, and no model sits anywhere in the aggregation path. The same rule governs our code: what may travel upstream is the generalized capability with its extension points, never a client's specific instantiation. This is that rule applied to knowledge.
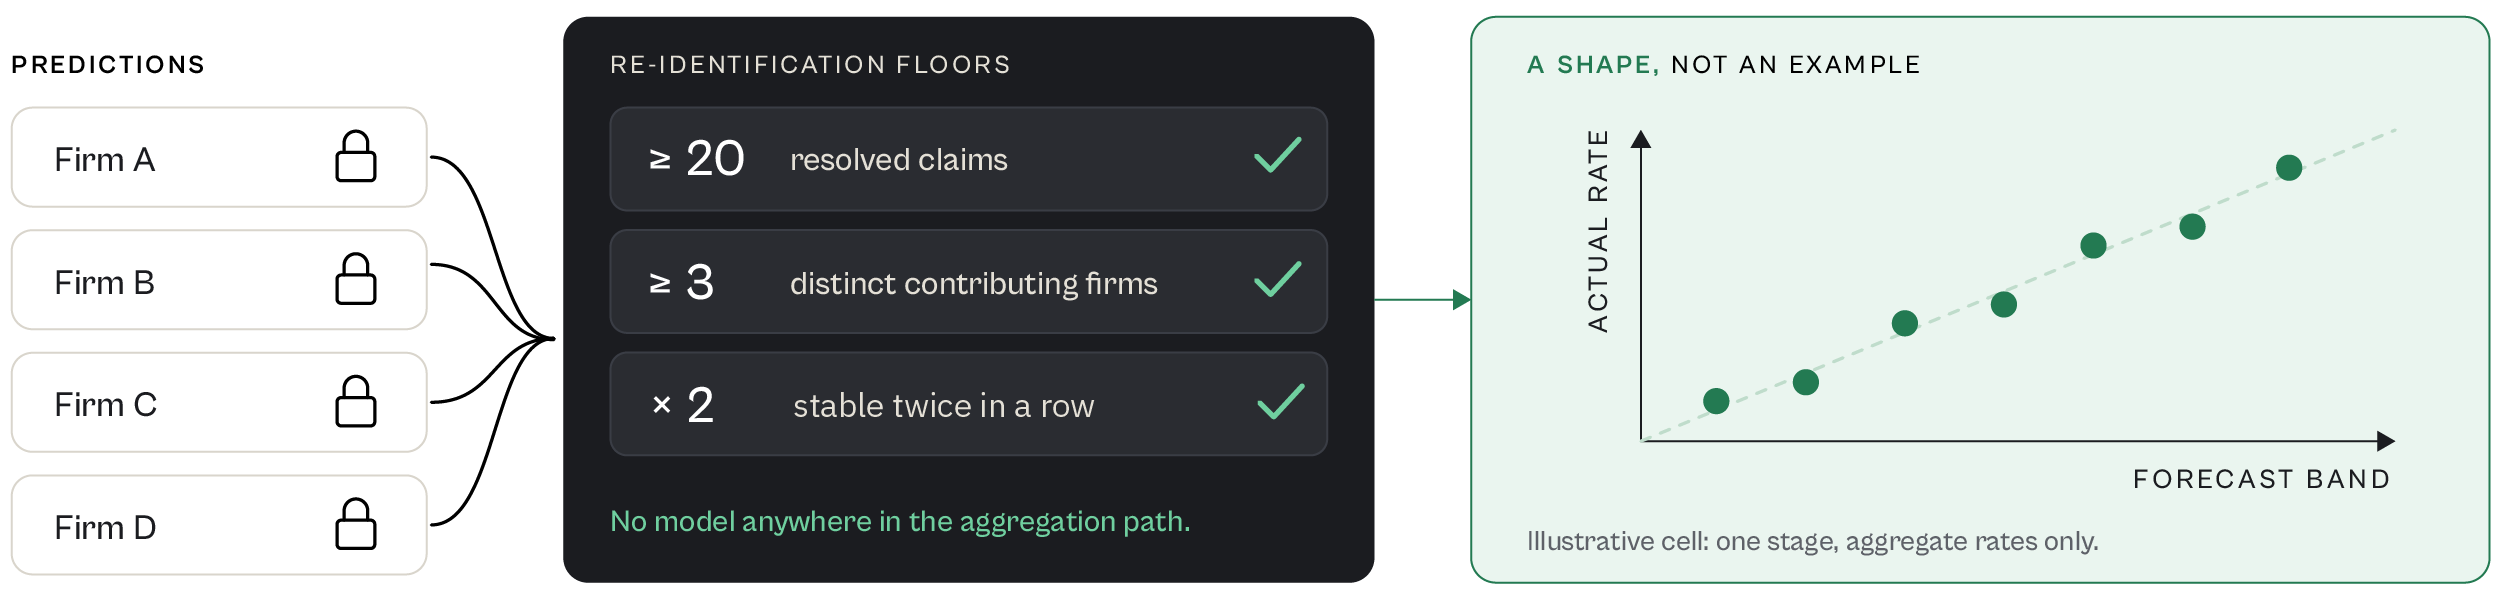
Which points at why we prefer in-context learning here, and the reason is governance before performance. For this class of problem, a well-retrieved memory block and a sharp learned rule already outperform a fine-tune on a thousand examples. But the deciding property is that the memory block can be read, versioned, attributed to the judgment that produced it, and deleted. A fine-tune can't be any of those things. For a client who may reasonably ask what the system has learned about them, and ask for it removed, that difference is the entire argument.
The machinery is built and the corpus is young
The failure mode of writing about a learning system is describing the architecture as though it were the accumulated result, so here is the status, exactly. The primitives are installed at the entry point every structured agent flows through. The prediction ledger is writing scored claims with their resolution specifications attached. The consolidation of injection into a single learning block is landing now, replacing the fragments individual agents currently build for themselves. What is young is the corpus. Track-record injection carries a deliberate floor, a minimum number of resolved claims before an agent sees its own record, and platform calibration carries a higher one, so that a small sample can't mislead. Those floors are correct, and they mean the loop runs at full strength only once resolution accumulates. We would rather describe the machinery accurately while the record behind it is thin than describe it grandly and be corrected by a client who looked.
What no architecture can shortcut is time. A learning system's value is the judgment it has accumulated and resolved, and resolution happens on reality's schedule: a raise window closes, a mark gets tested, a company exits or doesn't. That has a consequence worth sitting with. If lessons compound, and every lesson needs a resolved outcome to be earned, then a firm's accumulated record of audited machine judgment becomes an asset with the same properties as a track record: it can't be bought, faked, or hurried. Two firms can license the same models tomorrow. They can't license each other's resolved corpus.
Somewhere in the next few years, the interesting question in this market stops being whose agents can act, which is already commodity, and becomes whose agents have been wrong, on the record, often enough to be trusted. The reviews a partner writes this quarter are the seed of that answer. Anyone can build an agent that acts. Building one that gets better, in a way a client can audit and a person is accountable for, is the work, and the work has already started keeping score.
Vantage is the operating system for the modern venture firm: We put AI where it holds the asymmetric advantage and keep humans where they are irreplaceable. Book a demo with our team to see what it looks like.