Why Our Agents Have No Reward Function: Score Everything, Optimize Nothing
We score every claim our agents make, and we never let a score change an agent's behavior without a person in between. That second rule is the most consequential design decision we've made.

At Vantage, we build AI agents for venture firms. They forecast which portfolio companies will raise their next round, flag the ones drifting toward trouble, pull figures out of documents, and audit the assumptions behind investment decisions. Every falsifiable claim an agent makes gets scored once it resolves, and those scores add up to a track record.
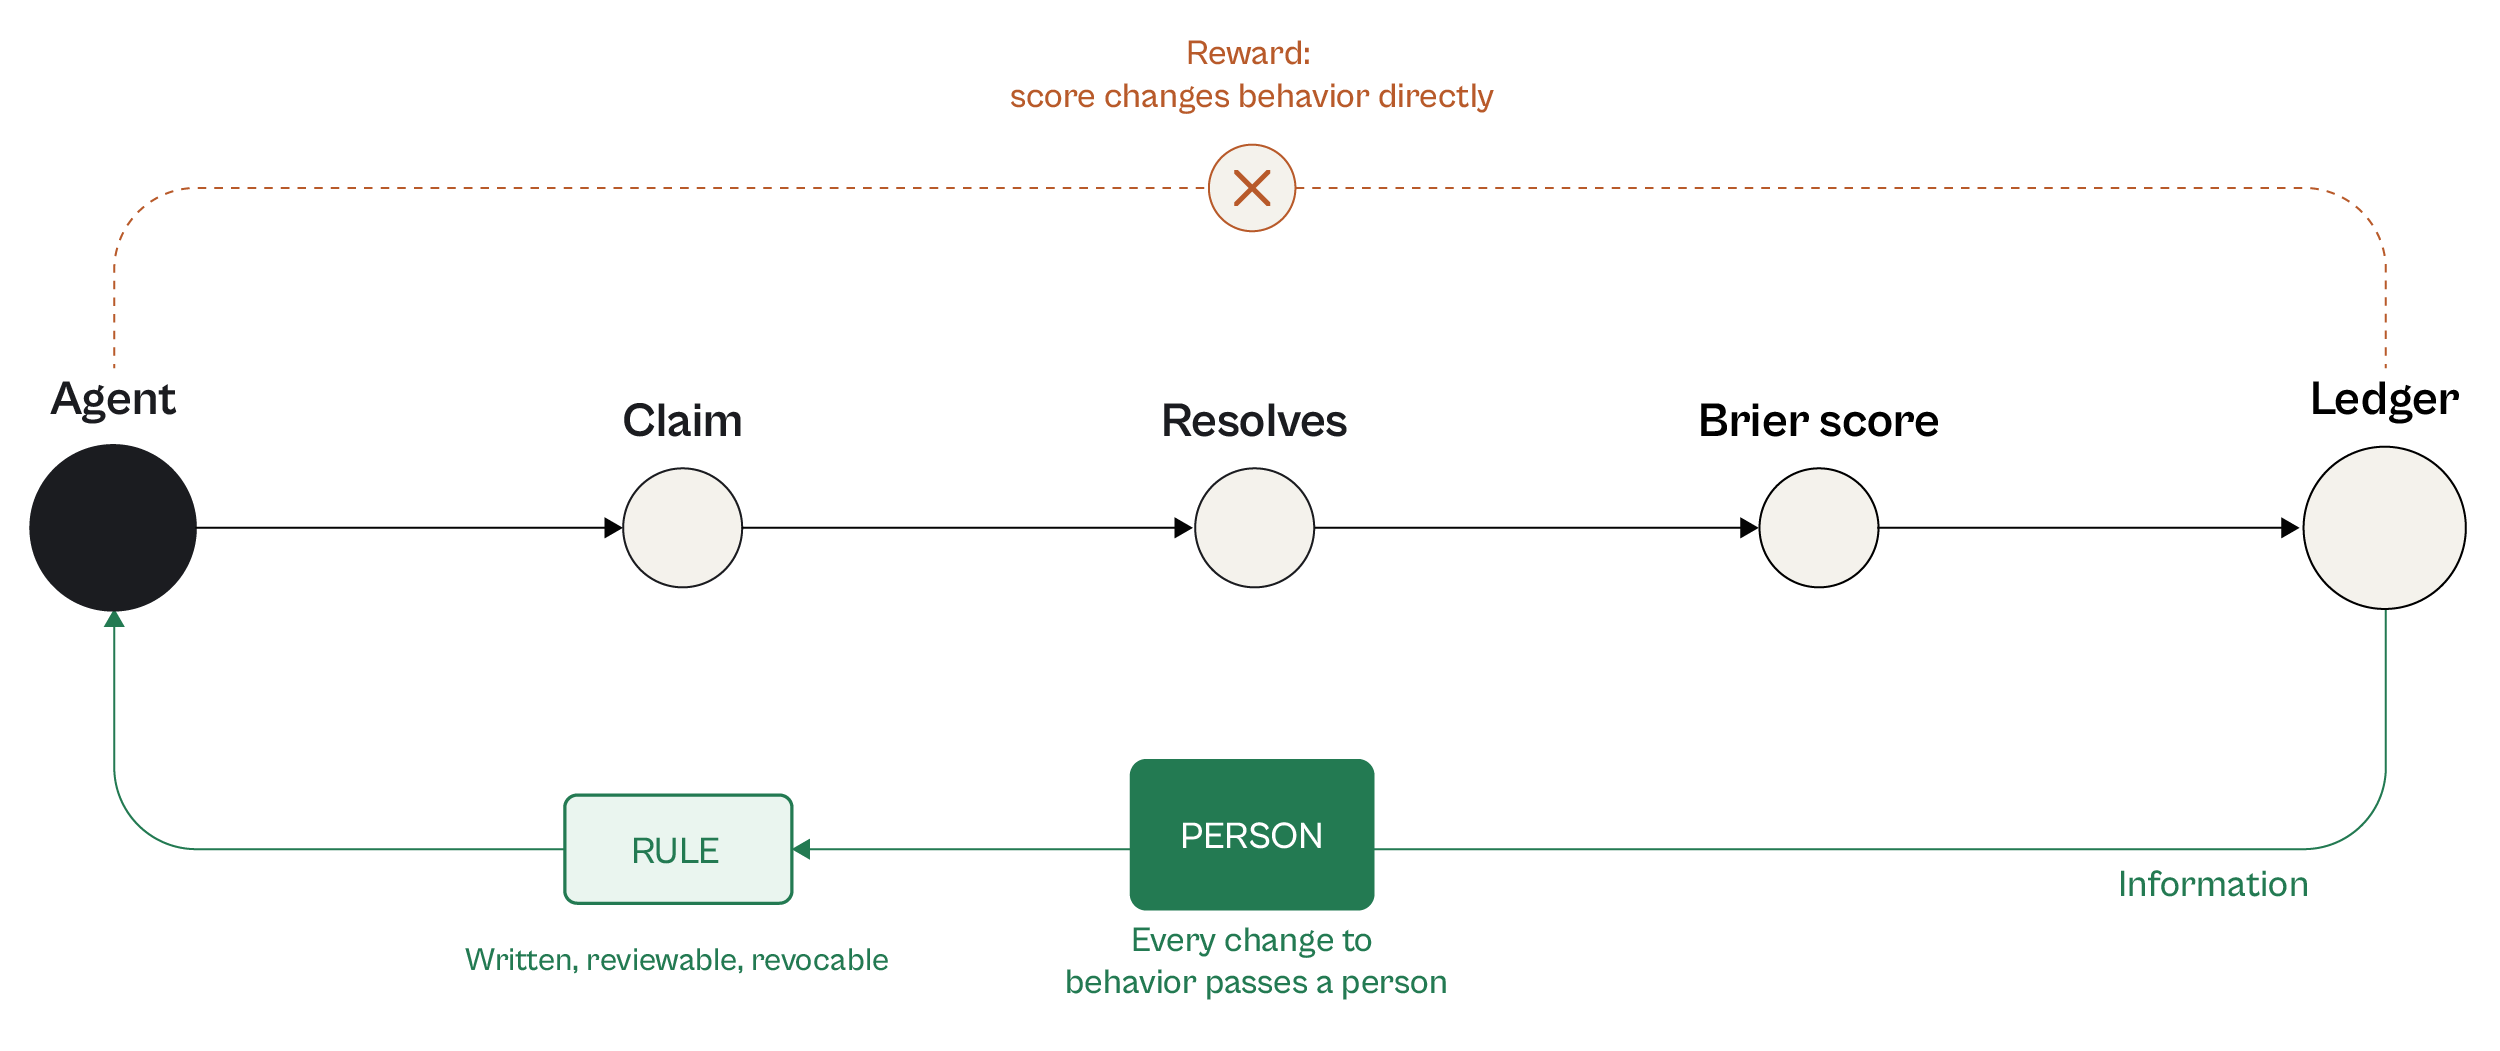
That detail reliably draws the same question from anyone technical: what's the reward function, the score the agents are trained to maximize? We don't have one, and we don't intend to build one. We score everything, and we never let a score change an agent's behavior without a person in between. The gap between those two commitments is the most consequential design decision in the platform.
We couldn't close the loop if we wanted to
Start with mechanics. Vantage doesn't train models. We call hosted frontier models through an API. There are no weights we update, no policy we optimize, and no gradient for a reward signal to attach to. There's nothing inside the model for us to adjust. Anything we called a reward would be a number in a database row. It would either inform a person or get fed into a prompt as context. The vocabulary of reinforcement learning doesn't describe what's available to us.
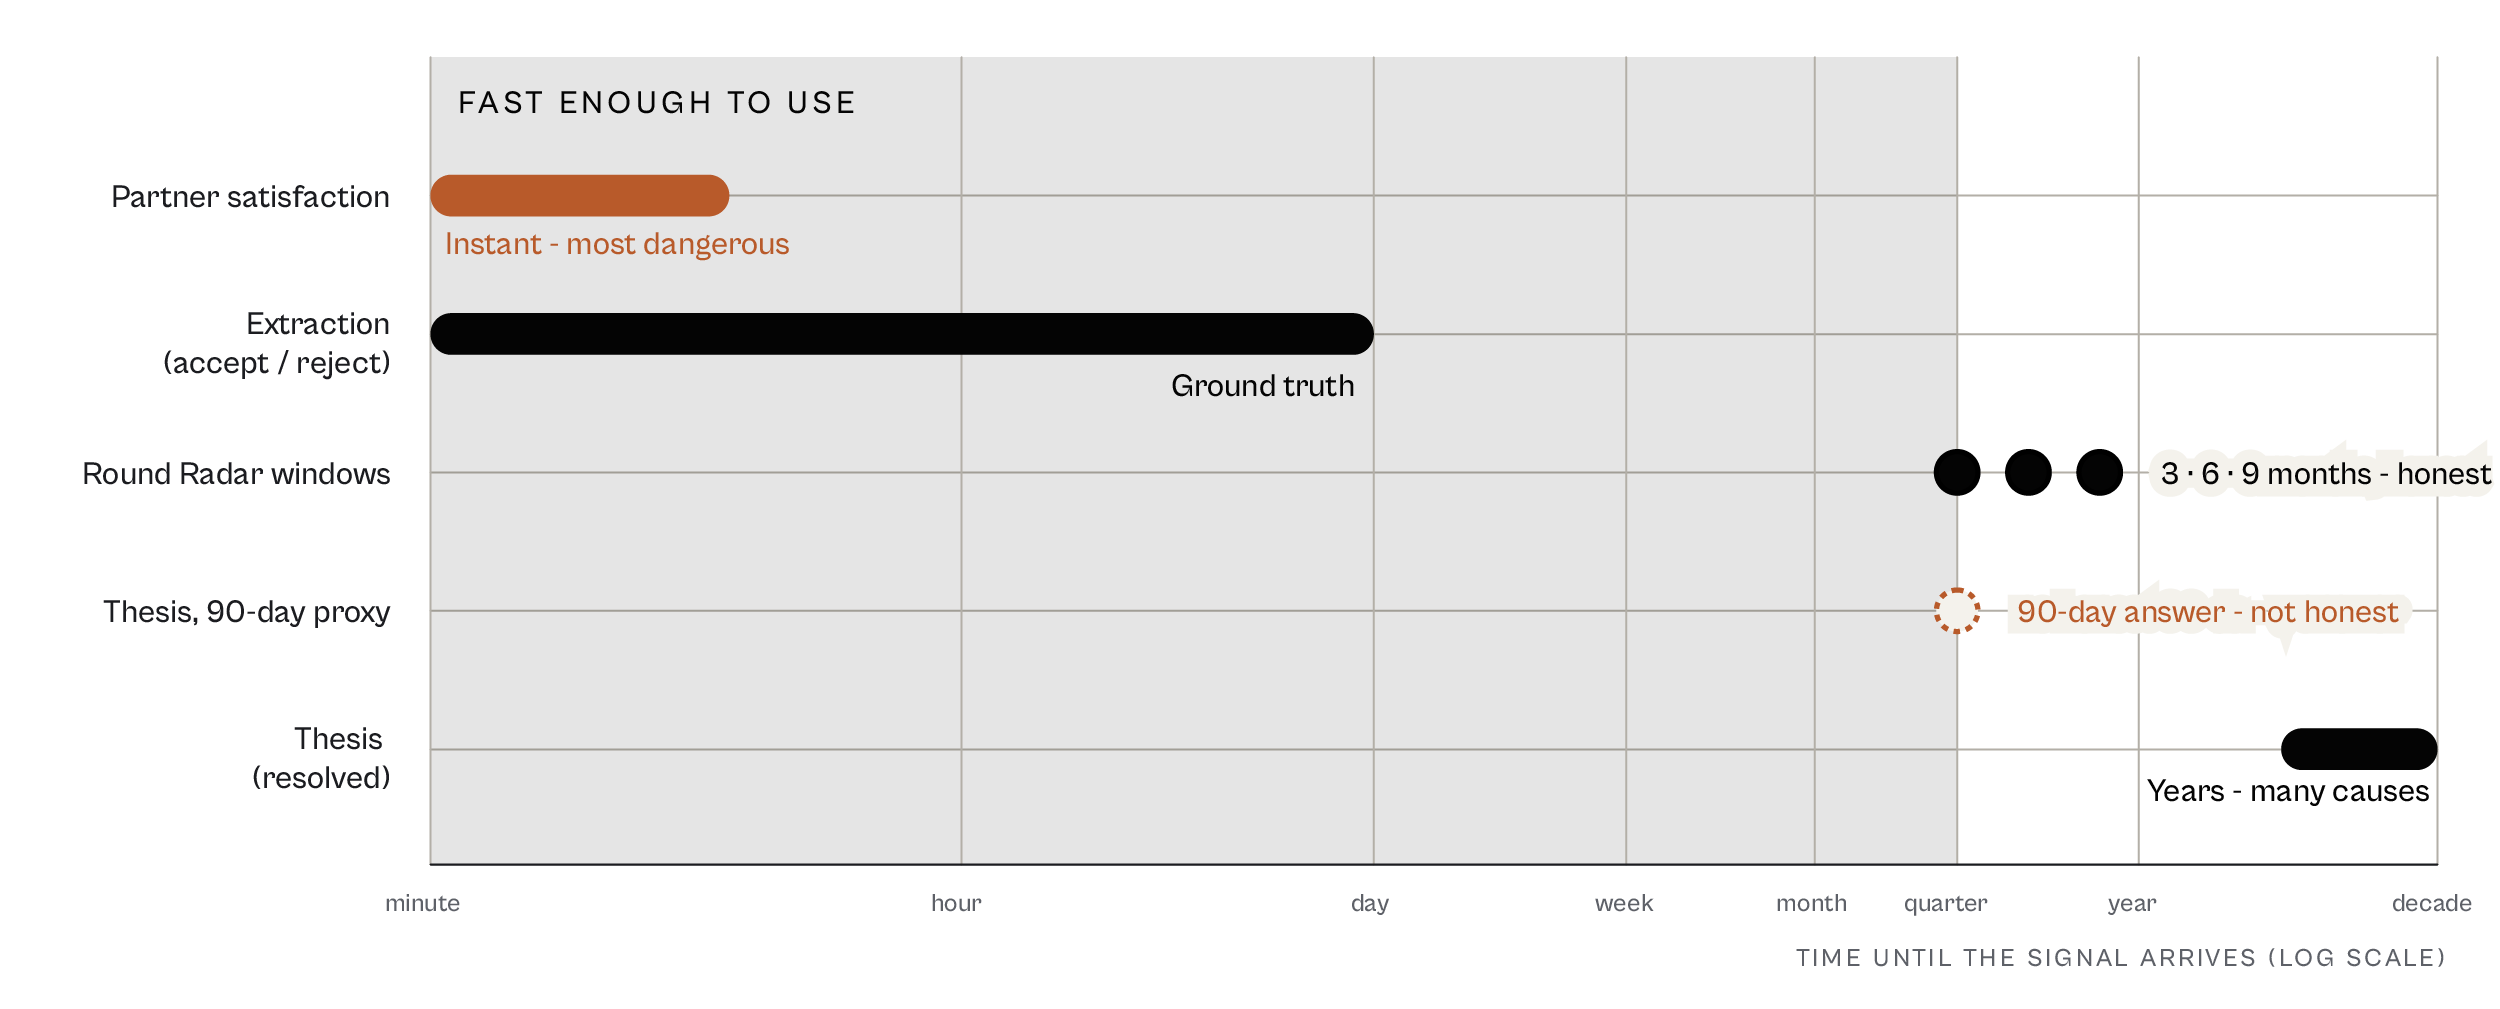
That constraint turns out to be fortunate, because venture is close to the worst possible place to close an optimization loop. Every reward signal we could compute is either too slow to use or too easy to game, and usually both.
The scoring half already exists
Our prediction ledger scores claims properly. An agent commits to a falsifiable statement with a probability attached. When reality resolves it, the claim closes with a Brier score: one minus the squared difference between the stated probability and the outcome. A confident correct call earns more than a timid one, and a confident wrong call pays for it. A call that refuses to commit earns what a coin flip would. It doesn't get to escape judgment the way an unfalsifiable statement does.
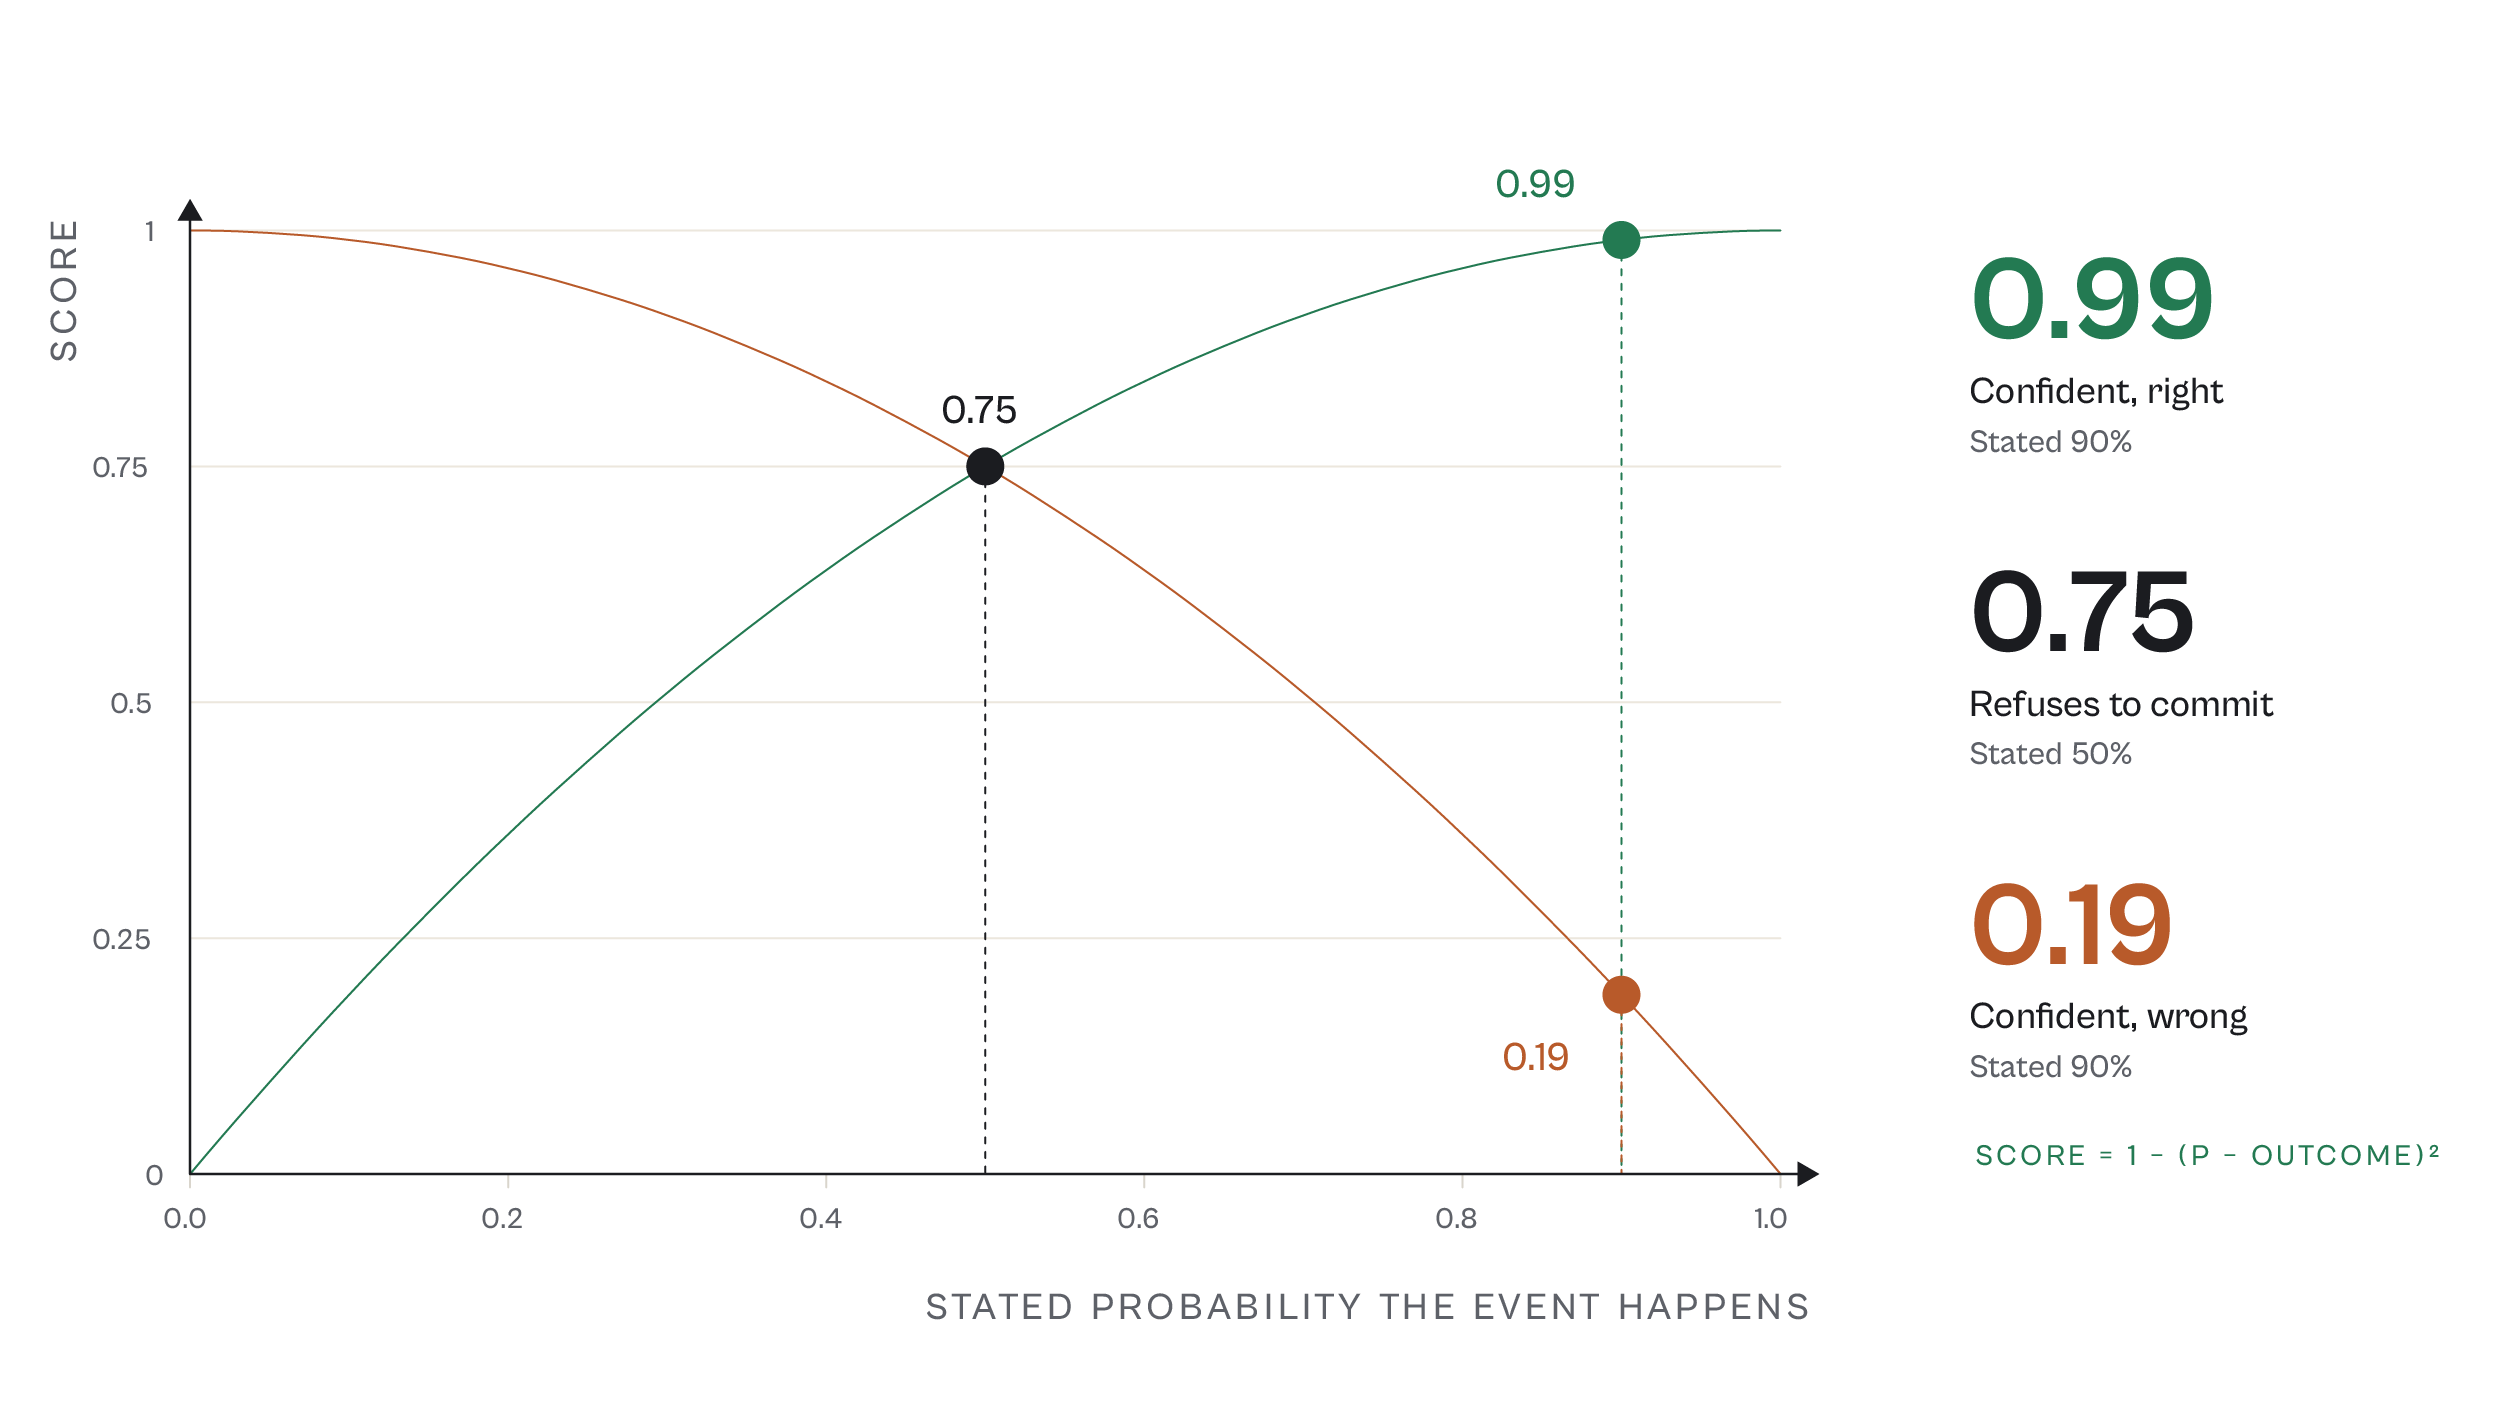
Every claim also carries a stamp showing which version of the agent made it and which version of the scorer graded it. A change in either can be traced instead of silently rewriting history. Those stamps show we were already thinking about gaming when we built the ledger. The danger starts when the score gets to steer.
The Brier score has a cheap half and an expensive half
The obvious objection is that the Brier score is a proper scoring rule. An agent maximizes its expected score by reporting exactly what it believes. Honest reporting is the optimal strategy, and no clever hedge beats the truth. How could optimizing on it produce anything but a more honest agent?
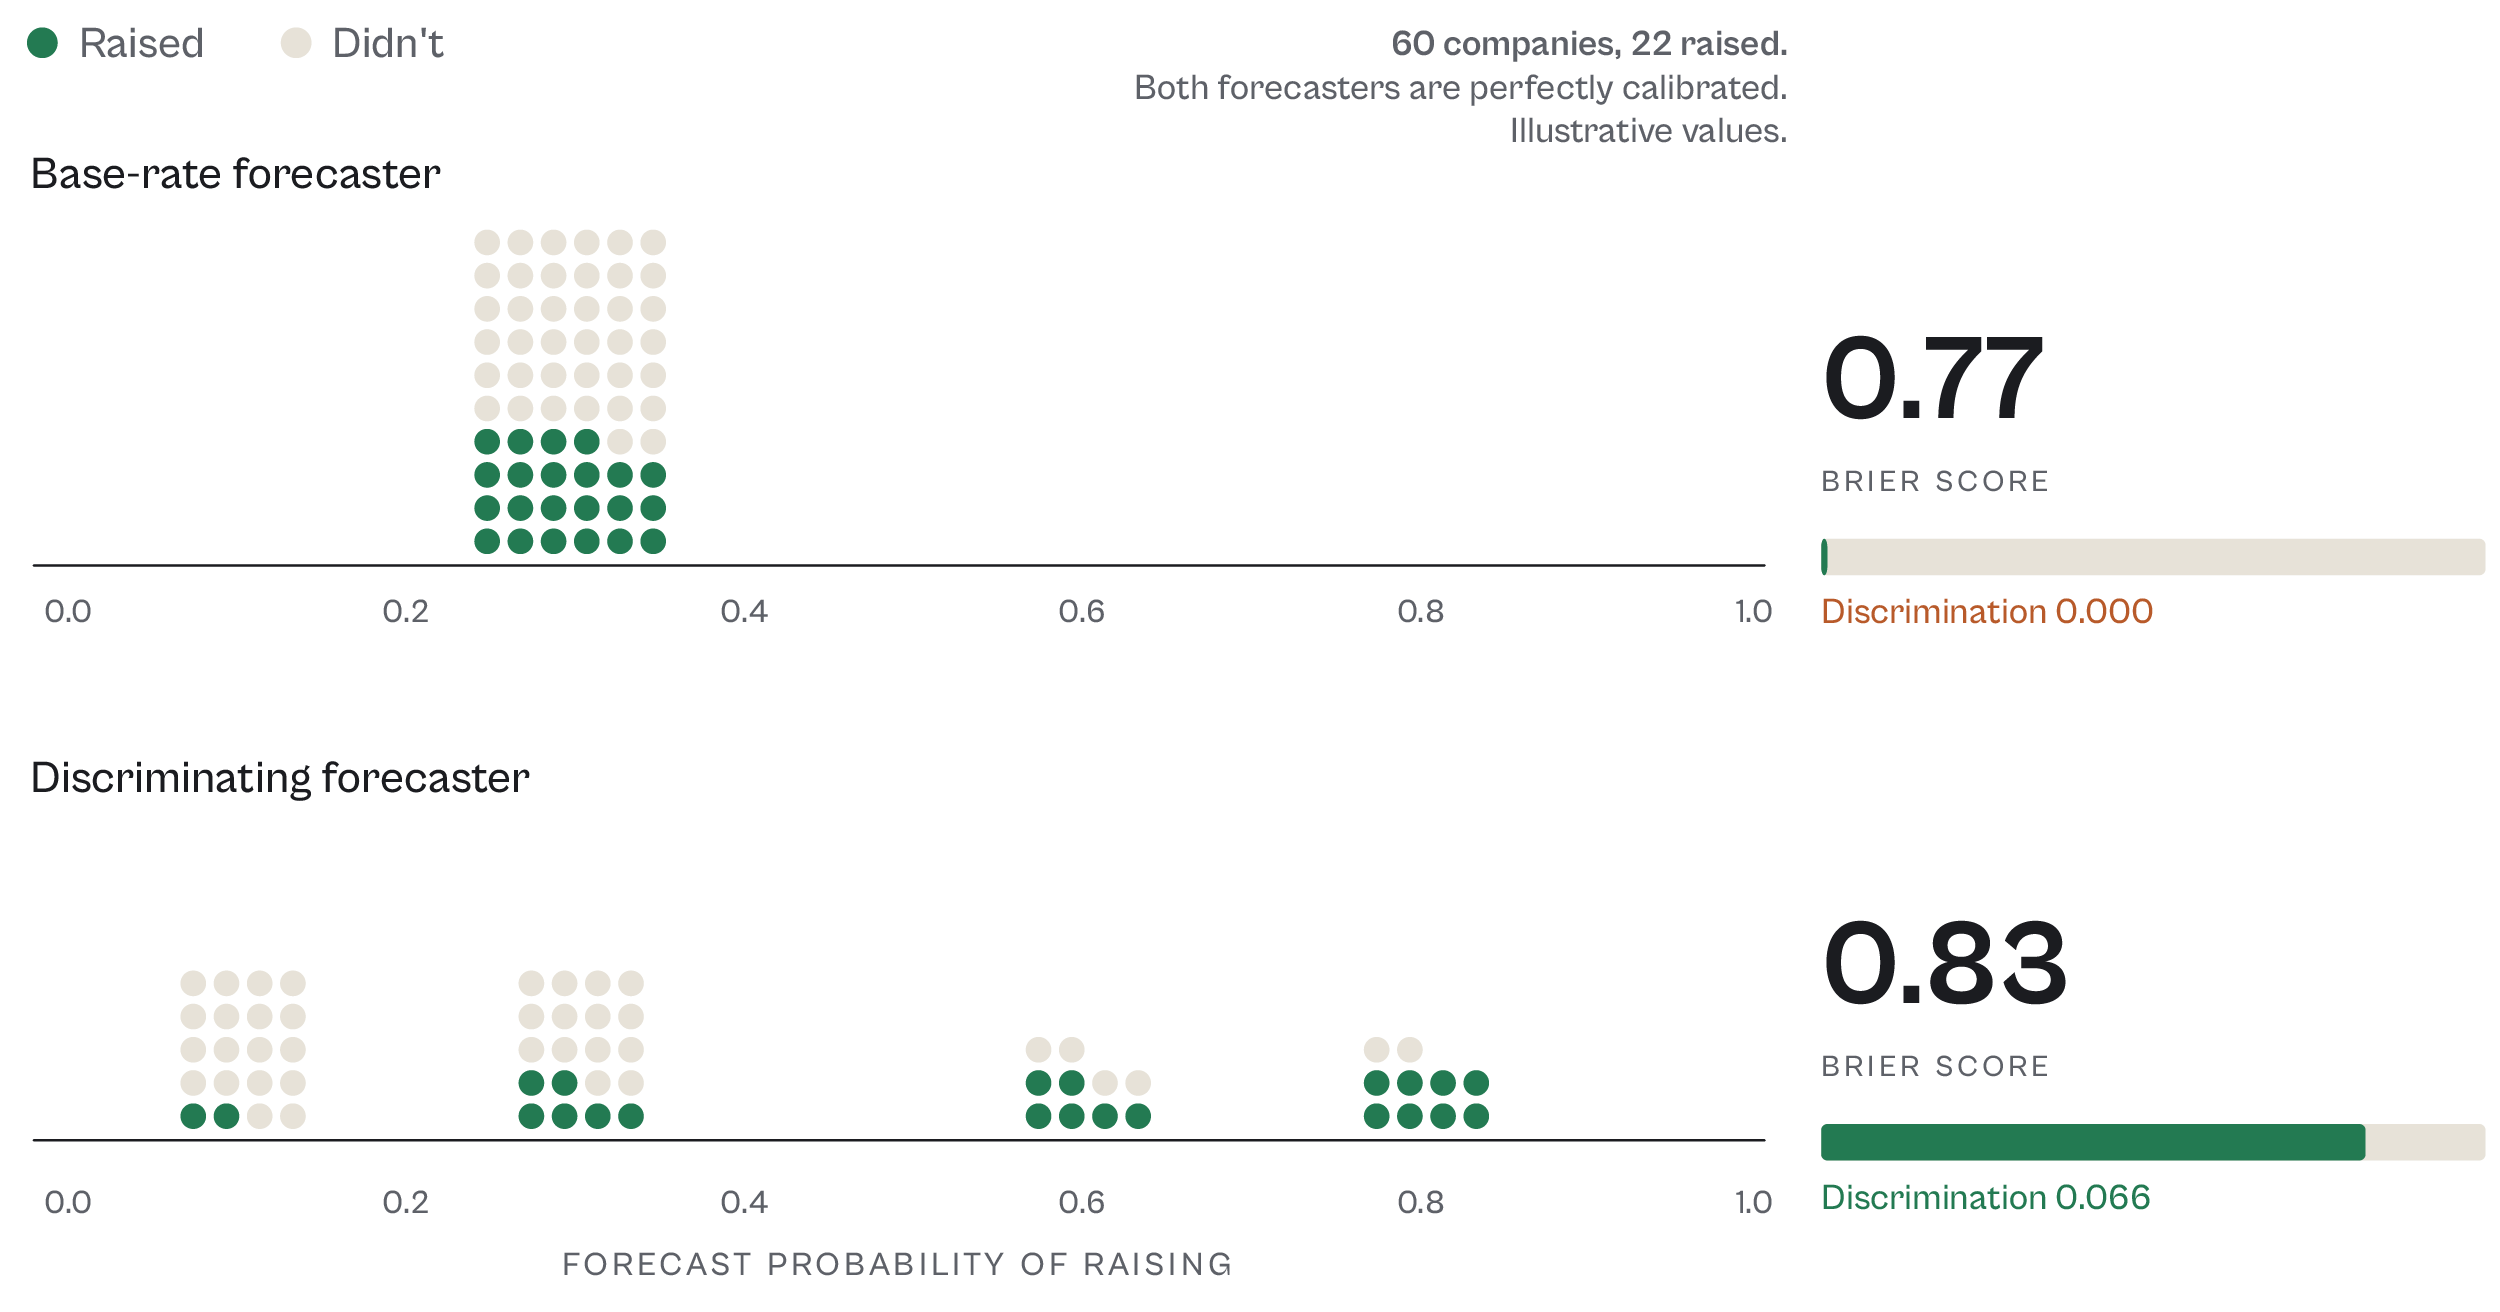
Because the score breaks into two parts, and they aren't equally hard to earn. Calibration asks whether the things an agent called 70% likely happen about 70% of the time. Discrimination asks whether the agent told you anything about the specific company in front of it.
Picture an agent that forecasts the base rate for every company in the portfolio. It's perfectly calibrated and has zero discrimination. It will score respectably and tell you nothing. A single number can't distinguish that agent from one that actually separated the company about to raise from the company about to run out of runway, because both land in roughly the same place. The scoring rule does stop an agent from hedging. What it can't stop is an agent learning to buy the cheap half of the score, skip the expensive half, and have the metric record the result as success.
Every reward we could compute would be gamed, and we can name how
The general argument is Goodhart's law: a measure that becomes a target stops being a good measure. Here's how it would play out, agent by agent.
Round Radar forecasts whether a company will raise within three, six, or nine months. Optimized on forecast accuracy, it would stop discriminating. It would converge on the base rate for each stage and collect a defensible score while carrying no company-specific information. The scoring catches a forecast that visibly waffles. It can't catch a forecast that's well calibrated and identical every time.
Pulse flags portfolio companies showing signs of trouble. Optimized on flags that turned out to matter, it would learn to stay quiet. Every flag is a chance to be wrong, so the way to protect a hit rate is to raise fewer. The metric improves as the agent gets more selective. Meanwhile, the flag it declines to raise is the one that mattered, because ambiguous cases are exactly where portfolio companies get into trouble.
A conversational agent that answers partners' questions about the portfolio would become sycophantic if optimized on partner satisfaction. Here, that breaks the product. Its whole value is its willingness to tell a partner something they'd rather not hear. One of ours recently told a partner that no source it could find supported a founder's headline claim about market position. It also reported that a cap table the firm had marked as current was three years stale. Neither message made anyone happy, and both were right. Preference optimization breeds that behavior out while the satisfaction score climbs.
Extraction agents pull figures from documents. Optimized on how often people accept their output, they would learn to skip the hard fields. An ambiguous figure on a badly scanned page is a chance to be rejected. A blank field isn't. So the agent extracts what it's sure of, acceptance rises, and coverage collapses while the dashboard reports improvement.
The Memo Analyst audits the load-bearing assumptions behind an investment committee's decision. Optimized on how often its verdicts hold up, it would learn to soften those assumptions, since a vaguer assumption is harder to mark broken. Eventually it would be writing assumptions that can't fail.
Every one of them makes the number better and the product worse.
Two features of venture make this worse than it is elsewhere
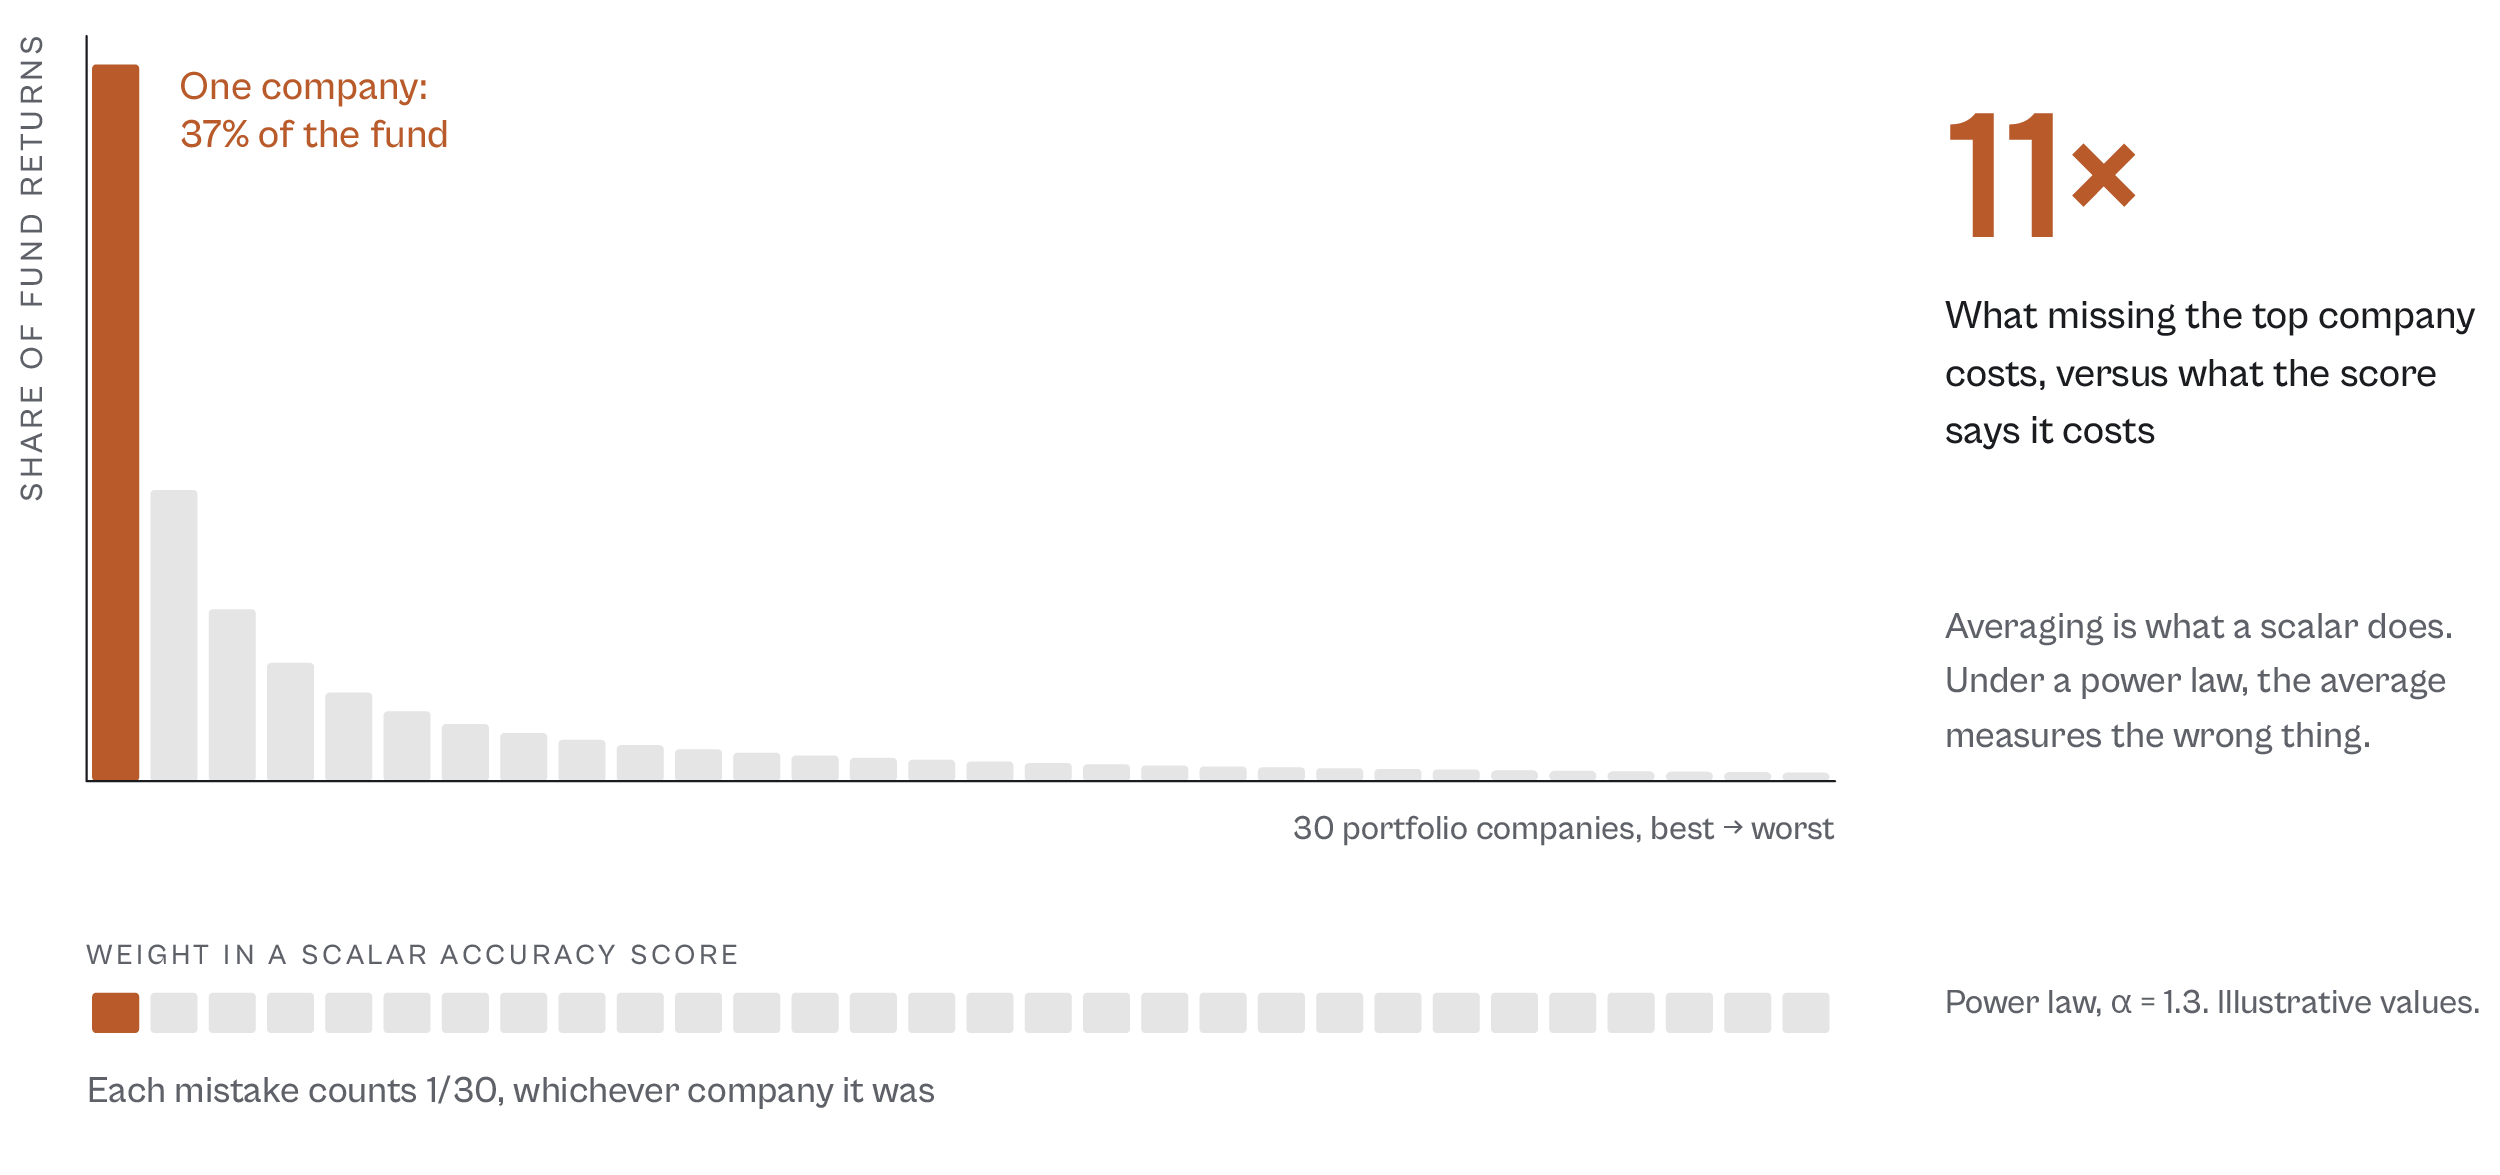
Reward hacking is a general problem. Two properties of allocating capital push it past the point where the usual fixes help.
The right answer depends on what kind of agent you are asking about
Our agents fall into three types, and each has access to a different kind of feedback.
| THE ARCHETYPE | WHAT FEEDBACK IT HAS | WHAT THAT PERMITS |
|---|---|---|
| Extraction agents | Ground truth. The document says what it says. A person accepting or rejecting an extracted value is a clean label with no judgment call in it. | The one place a training signal is safe, because there's a fact of the matter. Accept-and-reject pairs are legitimate material for eventual fine-tuning. The Goodhart risk is low, as long as coverage is watched alongside accuracy. |
| Analytical agents | Outcomes, but delayed, confounded, and asymmetric. A thesis is vindicated or broken years later, by events with many causes. | Scoring, with the score fed back as information rather than pressure. The agent reads its own record in context and adjusts its confidence. Nothing optimizes anything, and the record stays legible to a person who wants to argue with it. |
| Conversational agents | Preference signals only: whether the person liked the answer. That's the most dangerous feedback available and the easiest to collect. | No optimization, ever. Improvement comes from rules a person wrote, reviewed, and can revoke. That's why a named human gates every every rule in our learning loop. |
Most of our agents sit in the middle row, which turns on a small distinction. We tell an agent that when it forecast a probability in a given band, the event occurred at a given rate. That's a sentence in its context, offered the way a colleague offers a correction, and the agent isn't trying to maximize anything with it. It can disregard the sentence. If it does so wrongly, a person sees that too.
Four of those five failures look identical from outside
Go back to Pulse going quiet, extraction skipping ambiguous fields, the Memo Analyst softening assumptions, and Round Radar retreating to the base rate. In every case, accuracy holds steady or improves. The agent stays just as correct about what it addresses. It addresses fewer things, or addresses them less specifically, and an accuracy metric has no way to register either.
So a monitoring setup that watches hit rate will never see it. The record looks fine until someone notices one of three things: the flags stopped coming, a third of the fields on every parsed document are blank, or a set of thesis assumptions has become impossible to falsify.
Accuracy alone isn't enough. The missing measurements are coverage and abstention. How much of the available ground did this agent actually address? How often did it decline? Is it declining more than it used to, and if so, on what? Those two series make a strategic retreat visible. They belong next to the accuracy number, not in a separate report nobody opens.
Selection pressure belongs on the rules, not on the agents
None of this means nothing improves. There is selection pressure in the system, and it operates on rules.
A candidate lesson is variation: something that might be true and might be worth keeping. Corroboration across several firms, plus a person deciding to promote the lesson, is selection. A regression test that keeps a promoted rule from being silently lost later is retention. Variation, selection, and retention make an evolutionary loop. This one is discrete, auditable, and gated by a human at every step that matters. A lesson works its way up from an observation, to a stored record, to a rule in an agent's prompt, and ideally to a line of deterministic code where it's simply true.
What improves is the playbook. The model belongs to someone else, and the agents have no weights for us to move. They get better because the playbook they read got better. Every firm already runs this system. You don't give a junior analyst a reward function. You review their work and tell them what was wrong and why. Their good judgment gets written into how the team does things. Nobody had to design an objective function. That mechanism is a lot older than machine learning, and it's the right one here.
The work is closing resolution, not designing rewards
The scoring machinery exists. The gap is that claims are being written far faster than they're being resolved, so the signal isn't arriving yet. An agent doesn't see its own track record until a minimum number of its claims have resolved, so that a small sample can't mislead it. Calibrating the platform as a whole requires a higher floor still. Those floors are correct. They also mean the loop we designed won't run at full volume until resolution catches up. Showing more of our agents their own records comes after that.
That's a less exciting answer than a reward function. A closed optimization loop is the most tempting thing available to anyone building on models, because it promises improvement without anyone having to exercise judgment. The loop always delivers half of that promise: the number goes up. Whether the agent got better is a separate question. In venture, the costliest mistakes are rare and the verdict takes a decade. The most useful thing an agent can do is say something unwelcome. Only a person can answer that question.
Vantage scores every claim its agents make, shows those scores to the people accountable for the decisions, and lets no number change an agent's behavior without a human deciding it should. The machines take the coverage. Your team keeps the conviction.
Conviction Made Citable.